


Summary: The hardest part of acoustic echo cancellation isn’t choosing the right algorithm, but reliably capturing and synchronizing microphone and meeting audio so echo cancellation can work. A desktop recording SDK handles audio capture, synchronization and built-in AEC, so you don’t have to build and maintain that infrastructure yourself.
Acoustic echo cancellation (AEC) is a technique that reduces echo in meeting recordings. Echo can occur when audio from the speakers get picked up by the microphone, which can happen when the participant don't use headphones.
Echo cancellation is the general technique of removing echo, while acoustic echo cancellation (AEC) specifically addresses echo caused by speaker-to-microphone feedback, which is a source of echo in desktop meeting recordings.
This blog explores the different approaches to eliminate acoustic echo cancellation, explain their benefits and limitations, and if certain audio capture infrastructure can reduce the need for developers building desktop meeting recorders.
How to apply acoustic echo cancellation on macOS: Core Audio, AVCapture session, Audio Toolbox, ScreenCaptureKit
When building the audio infrastructure for desktop meeting recording on macOS, developers can use Apple's built-in frameworks, such as Core Audio, AVCaptureSession, and ScreenCaptureKit. They can capture both microphone and meeting audio streams.
System audio refers to all audio played by a computer. Outgoing application audio refers to audio played by a specific application, while meeting audio is a subset of application audio that comes from a meeting application like Zoom, Google Meet or Teams meeting.
However, none of these frameworks automatically apply acoustic echo cancellation to the captured audio streams. So developers need to use a third-party solution like WebRTC or Apple’s native options, such as Core Audio’s VoiceProcessingIO or AVAudioEngine’s voice processing capabilities.
Core Audio and AVAudioEngine have the same underlying technology, so they have the same capabilities and limitations. The main difference lies in how developers access them.
If you’re already using AVAudioEngine to capture microphone audio, enabling AEC is straightforward:
let engine = AVAudioEngine()

try engine.inputNode.setVoiceProcessingEnabled(true)
AVAudioEngine handles the underlying audio input and output configuration required for acoustic echo cancellation automatically, making AEC easier to implement.
In contrast, VoiceProcessingIO requires more manual setup through Apple’s lower-level Audio Unit APIs. Developers need to create and configure a VoiceProcessingIO audio unit, set audio formats, and manage audio callbacks, all of which are steps that AVAudioEngine handles automatically.
When building audio infrastructure on Windows, developers can use Microsoft’s built-in APIs such as Windows Audio Session API (WASAPI) and WASAPI Loopback Recording.
However, both options have limitations for acoustic echo cancellation in desktop meeting recorders, whether they’re built with Electron or Tauri. Apple’s native AEC options, such as VoiceProcessingIO and AVAudioEngine’s voice processing, are integrated into the live audio input and output pipeline. They aren’t post-processors that developers can simply pass microphone and meeting audio streams into.
For desktop meeting recorders that already have an audio capture pipeline, adopting Apple’s native AEC may require restructuring how microphone audio is captured and processed, rather than simply adding echo cancellation to the existing streams. Alternatively, WebRTC’s Audio Processing Module offers more flexibility, but developers using it still need to capture, format, and synchronize the microphone and meeting audio streams themselves.
Using WebRTC for acoustic echo cancellation on macOS
WebRTC is an open-source audio and video framework that includes audio processing features such as acoustic echo cancellation (AEC). Unlike native macOS solutions, WebRTC can directly process microphone and meeting audio streams.
WebRTC uses the AEC3 algorithm to reduce acoustic echo. AEC3 uses meeting audio as a reference, comparing the meeting audio with the microphone audio stream to estimate the delay and identify the echo. It then uses those estimates to remove the echo from the microphone audio stream.
// Pseudocode
while (recording) {

    // 1. Get audio captured by macOS
    AudioFrame zoomAudio = getNextZoomAudioFrame();
    AudioFrame micAudio  = getNextMicrophoneFrame();

    // 2. Supply Zoom audio as the echo reference
    apm->ProcessReverseStream(&zoomAudio);

    // 3. Remove estimated echo from microphone audio
    apm->ProcessStream(&micAudio);

    // 4. Save the cleaned mic with the original Zoom audio
    saveAudio(originalZoomAudio, micAudio);
}
Developers can also use another third-party AEC tool called GStreamer. However, for desktop meeting recorders with an existing audio capture pipeline, adopting GStreamer requires building and integrating a brand new audio pipeline.
Is WebRTC better suited than GStreamer for desktop meeting recording?
GStreamer is an open-source multimedia framework for processing and streaming audio and video that supports acoustic echo cancellation (AEC). Unlike WebRTC, it requires developers to build and manage an audio and video processing pipeline within its framework, making it less flexible for applications with an existing audio capture pipeline.
For desktop meeting recorders that already have an audio capture pipeline built using ScreenCaptureKit or Core Audio, GStreamer adds unnecessary complexity. Developers need to route their existing audio streams into GStreamer’s pipeline.
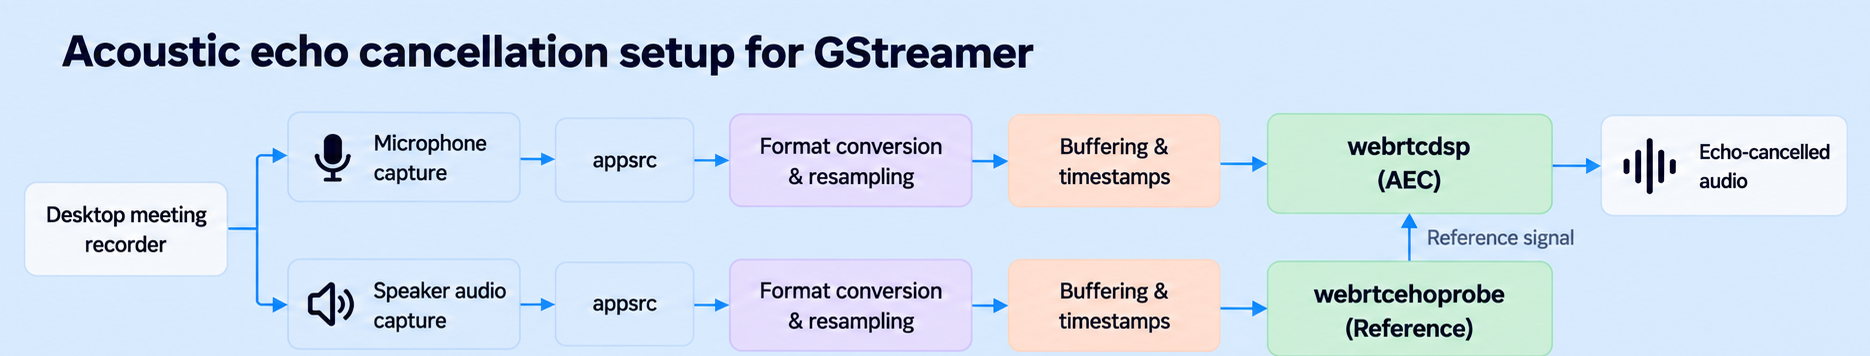
Since GStreamer enables echo cancellation through its WebRTC-based webrtcdsp plugin, developers with an existing audio capture pipeline may prefer to cut out the middleman and just use WebRTC. WebRTC allows developers to route audio streams into WebRTC’s pipeline and apply acoustic echo cancellation (AEC), without having to rebuild their entire audio capture pipeline. However, if your application already uses GStreamer, there is no need to build an additional framework. Additionally, if your application needs additional multimedia processing features, such as audio mixing, encoding, or streaming, GStreamer can be a good option.
Regardless of which approach you choose, you need to ensure that your microphone and speaker audio streams are properly captured, synchronized, and formatted. Otherwise, you will run into significant challenges getting echo cancellation to work.
Challenges you’ll run into using WebRTC
The main challenge with using WebRTC isn’t implementing AEC itself, but ensuring the audio streams are properly synchronized correctly before funneling them into WebRTC for processing. Without proper audio synchronization, acoustic echo cancellation will not work.
However, when building a desktop meeting recorder for applications like Zoom or Google Meet, developers don’t have full control over how audio is captured and played back. These applications manage their own audio input and output pipelines, making it more challenging to keep the microphone and meeting audio streams synchronized. As covered earlier, synchronized microphone and meeting audio streams are essential for acoustic echo cancellation.
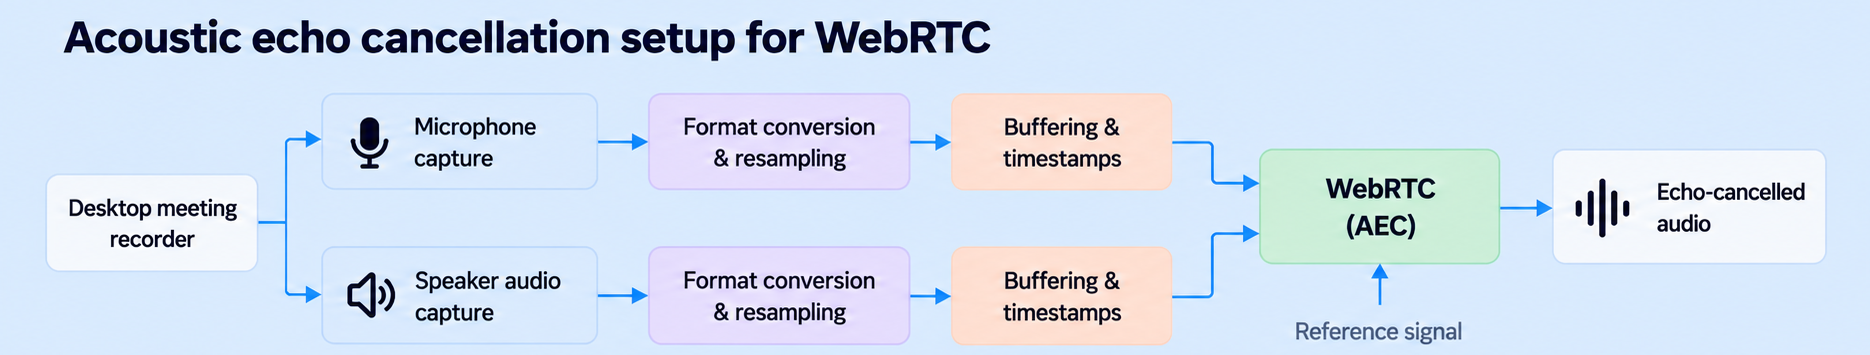
Because macOS’s capture APIs don’t provide a single method that works consistently across all supported macOS versions, developers need to use different APIs to capture microphone and meeting audio streams. As mentioned above, the streams can have different processing delays, buffering, and timing, making synchronization challenging. If the streams aren’t properly synchronized, WebRTC won’t be able to remove the echo.
Even when users are running a version of macOS that can use a single API, such as ScreenCaptureKit to capture both microphone and meeting audio, user behavior like switching between speakers or microphones during a meeting can change audio routing and timing. The switch between speakers and microphones makes it harder to keep audio streams synchronized and impacts acoustic echo cancellation. This is a common issue when users move to peripherals or connect devices like AirPods.
Developers can avoid the complexity of building the audio capture infrastructure and synchronizing audio streams by using a desktop recording SDK that handles these processes.
Built-in acoustic echo cancellation using the Desktop Recording SDK
A desktop recording SDK already has the audio capture infrastructure and acoustic echo cancellation built in to record meetings across platforms like Zoom, Google Meet and Microsoft Teams, allowing developers to get high-quality audio without echo, clear video recordings, and meeting data such as speaker-labeled transcripts.
The SDK also handles user behavior that disrupts audio routing and synchronization, such as switching microphones, changing audio output devices, or disconnecting Bluetooth headphones during a meeting. Recording quality is therefore maintained across different user behavior without developers having to build and manage the underlying audio infrastructure themselves.
Integrating the Desktop Recording SDK into your application takes just a few hours and you can get to production in a matter of days, whether you built the app with Electron or Tauri. The SDK also handles edge cases that make building recording infrastructure challenging, such as your end-user running out of storage space or running out of battery.
Much of the complexity of building a desktop meeting recorder comes from handling edge cases that often only surface in production, making them difficult to anticipate during development. One example is mute state detection, which involves determining whether a participant’s microphone is muted. It is a feature that can be overlooked, but is critical for preventing audio from being recorded when a user is muted and reduces privacy issues.
Whether you’re building with WebRTC or native macOS APIs, you’ll need to handle countless edge cases, which you can avoid by buying Recall.ai’s Desktop Recording SDK. Recall.ai handles these challenges out of the box, so your engineering team can focus on differentiating your product rather than maintaining recording infrastructure. It’s one of the reasons companies like ClickUp, monday.com, and HubSpot choose Recall.ai instead of building and maintaining their own recording solutions.
If you are interested in building on meeting data with Recall.ai, you can sign up for a free account.
Appendix
Comparing the different methods for Acoustic Echo Cancellation
| AVAudioEngine | VoiceProcessingIO | WebRTC | GStreamer | Recall.ai’s Desktop Recording SDK | |
|---|---|---|---|---|---|
| Time to implementation | A few hours | 1-2 days | Several days to weeks | Several days to weeks | A few hours |
| Acoustic echo cancellation | Apple's native AEC | Apple's native AEC | WebRTC AEC3 | WebRTC-based AEC | WebRTC-based AEC |
| Audio configuration | I/O setup is handled automatically | Requires I/O configuration | Requires audio format configuration | Requires configuring a GStreamer pipeline | Handled out of the box |
| Microphone selection | Uses the system default input | Manual selection through Core Audio | Managed through the application’s audio capture pipeline | Configured through GStreamer's audio source plugins | Automatic |
| Best suited for | Convenient for applications already Apple’s high-level audio APIs | Apps requiring low-level audio I/O configuration | Developers building custom pipelines | Apps built on GStreamer | Desktop meeting recorder |


